
MiniMax-2.5 Expert Offload and website generation
MiniMax-2.5 IQ5_K through IQ3_S: Expert Offload for local LLM integration and React landing-page and static-site web development examples.
Measurements and generated sites
MiniMax-2.5 (229B MoE, 8 active experts out of 256) ran on 96GB VRAM with -ot exps=CPU. IQ5_K decoded at 34-37 tok/s. I also generated a React landing page with IQ4_NL and a dental clinic static site with IQ3_S.
Test Environment
| Item | Specification |
|---|---|
| CPU | AMD EPYC 9175F (Zen 5, 16C/32T, L3 512MB) |
| GPU | NVIDIA RTX PRO 6000 Blackwell Max-Q (96GB VRAM) |
| Memory | DDR5-6400 768GB (12ch) |
| OS | Ubuntu 24.04 LTS |
| Runtime | ik_llama.cpp (build 4192) |
| Container | Podman rootless |
Model Specifications
| Item | Value |
|---|---|
| Architecture | MiniMax-M2 (MoE) |
| Size | 229B.A10B (229B total, 10B active) |
| Layers | 62 |
| Experts | 256 (8 active) |
| Training context | 196,608 |
| rope freq_base | 5,000,000 |
Part 1: Expert Offload Benchmark (IQ5_K)
Execution Command
  podman run --rm -it \
  --device nvidia.com/gpu=all \
  -p 8081:8080 \
  --shm-size 16g \
  --cap-add=SYS_NICE \
  -v "$MO":/models:ro,Z \
  $IMG \
  --host 0.0.0.0 --port 8080 \
  -m "$MODEL" \
  --no-mmap --jinja \
  -c 65536 \
  --threads 13 --threads-batch 25 \
  -b 2048 -ub 2048 \
  -ngl 99 \
  -ot exps=CPU \
  -ctk f16 -ctv f16 \
  --warmup-batch \
  -fa on
Key parameters:
-ot exps=CPU: Force Expert weights (bulk of 157GB) to CPU memory-ngl 99: Shows 63/63 layers GPU-offloaded, but Experts override via-ot--no-mmap: Pin 157GB in physical RAM, eliminate page faults--warmup-batch: Run warmup on startup
Memory Layout
| Region | Size | Location |
|---|---|---|
| CPU buffer (Expert weights) | 157,356 MiB (~154GB) | CPU RAM |
| KV cache | 15,872 MiB (~15.5GB) | CUDA0 |
| Compute buffer | 1,990 MiB | CUDA0 |
| GPU buffer (Attention, etc.) | 3,579 MiB | CUDA0 |
Actual GPU VRAM usage is ~21GB. The remaining 75GB is available for KV cache expansion.
Results: 8 Consecutive Runs (65K Context)
| Run | Prompt(tok) | PP(tok/s) | Gen(tok) | TG(tok/s) | Total(s) |
|---|---|---|---|---|---|
| 1 | 753 | 214.07 | 215 | 35.37 | 9.6 |
| 2 | 386 | 170.36 | 196 | 35.23 | 7.8 |
| 3 | 297 | 161.38 | 240 | 35.21 | 8.7 |
| 4 | 341 | 166.12 | 783 | 34.57 | 24.7 |
| 5 | 1,264 | 205.46 | 734 | 34.53 | 27.4 |
| 6 | 942 | 215.21 | 921 | 34.30 | 31.2 |
| 7 | 938 | 216.23 | 157 | 34.31 | 8.9 |
| 8 | 1,075 | 176.32 | 1,351 | 33.76 | 46.1 |
| Metric | PP(tok/s) | TG(tok/s) |
|---|---|---|
| Mean | 190.64 | 34.66 |
| Median | 190.89 | 34.55 |
| Min | 161.38 | 33.76 |
| Max | 216.23 | 35.37 |
Extended Session (131K Context)
| # | PP(tok) | TG(tok) | Ctx Used | PP(tok/s) | TG(tok/s) |
|---|---|---|---|---|---|
| 1 | 3,227 | 72 | 4,820 | 268.08 | 37.69 |
| 4 | 2,708 | 512 | 8,223 | 289.89 | 35.96 |
| 8 | 1,965 | 192 | 11,172 | 313.60 | 35.39 |
TG was 33.7-37.7 tok/s, without a sharp decline as context grew.
What Expert Offload showed
- Speed: TG varied about 10% across 8 runs, which I interpret as consistent PCIe rate-limiting.
- Offload display: “offloaded 63/63 layers to GPU” still leaves Expert weights on CPU through
-ot. - Prompt cache: 6,029 tokens used 1,460 MiB; 23,104 tokens used 5,596 MiB. Repeated runs shortened TTFT.
- Tokenizer warning:
special_eos_id is not in special_eog_idsleaves a risk of unstable EOG / EOS handling.
One-Prompt Generation Live Demonstration
The video records website generation from one prompt.
Video link: https://www.youtube.com/watch?v=zisR4hPfT2c
It shows AGENTS.md input, token-by-token speed, and the generated code.
Part 2: React LP One-Shot Generation (IQ4_NL)
Configuration
- Quantization: IQ4_NL (lighter than IQ5_K, quality nearly maintained)
- Context: 262,144 (256K)
- Input:
AGENTS.md(detailed site specification for loFT LLC) - Stack: Vite + React + TypeScript + Tailwind CSS v4
Results
The model generated the loFT LLC corporate site from AGENTS.md.
Generated component structure (Atomic Design):
- Atoms: Button, Heading, Text, Icon, Input, TextArea, Badge
- Molecules: ServiceCard, CaseStudyCard, TestimonialCard, NavItem
- Organisms: NavBar, HeroSection, ServiceGrid, ProcessTimeline, ContactForm, Footer
Implemented features:
- Hero section (animated background with function curves)
- Contact form (
react-hook-form+zodvalidation) - SEO optimization (JSON-LD structured data, dynamic meta tags, favicon generation)
- SPA routing (
react-router-dom)
Tailwind v4 repair
After npx tailwindcss init failed, the model switched from the old tailwind.config.js approach to CSS-first @import "tailwindcss";.
TypeScript error handling: The first build attempt produced 18 TypeScript errors falling into predictable groups:
- Prop and routing mismatch (
LegalPagedesigned one way, consumed another) import typerequired underverbatimModuleSyntax- Callback typing inconsistencies (
onClick?: () => voidvs(e: any) => void) React.cloneElementtyping issues- Unused imports after refactoring
One repair cycle from the build logs made the build pass.
  vite v7.3.1 building client environment for production...
✓ 147 modules transformed.
dist/index.html                   0.46 kB │ gzip:   0.29 kB
dist/assets/index-BeGmd-zS.css   30.76 kB │ gzip:   5.99 kB
dist/assets/index-CCc5Lf0B.js   357.41 kB │ gzip: 111.66 kB
✓ built in 797ms
The session checked the dev server with lsof -i :5173, obtained HTML with curl, and updated title, description, OGP, and favicon. The generated web development artifact was ready for browser inspection.
Part 3: Dental Clinic Static Site (IQ3_S GPU Full Load)
Why IQ3_S
I traded some precision for more GPU-resident Expert weights and less -ot exps=CPU latency.
Requirements
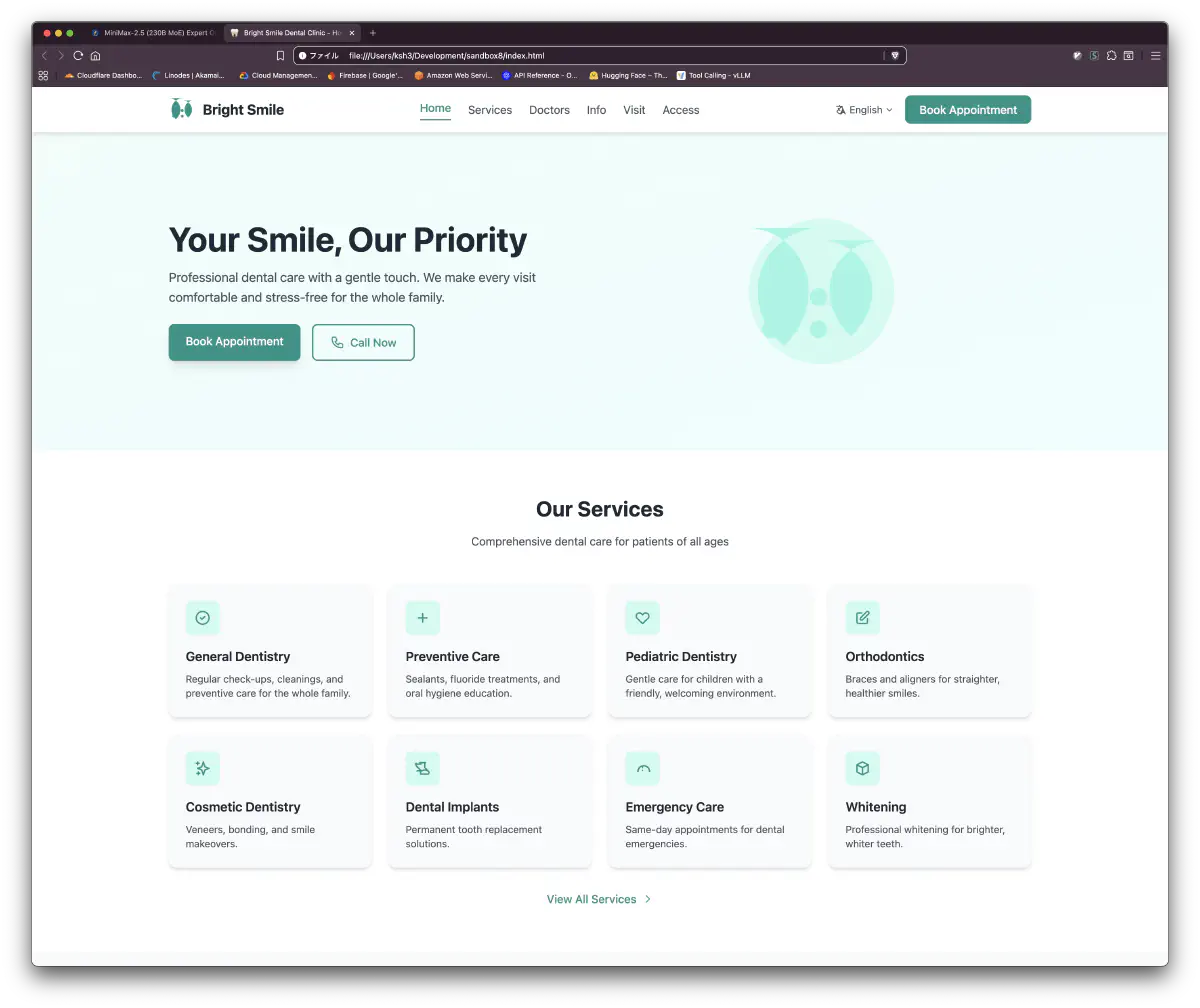
- 6-page static HTML site (index, services, doctors, info, visit, access)
- No build step, Tailwind CSS (CDN), Alpine.js (CDN)
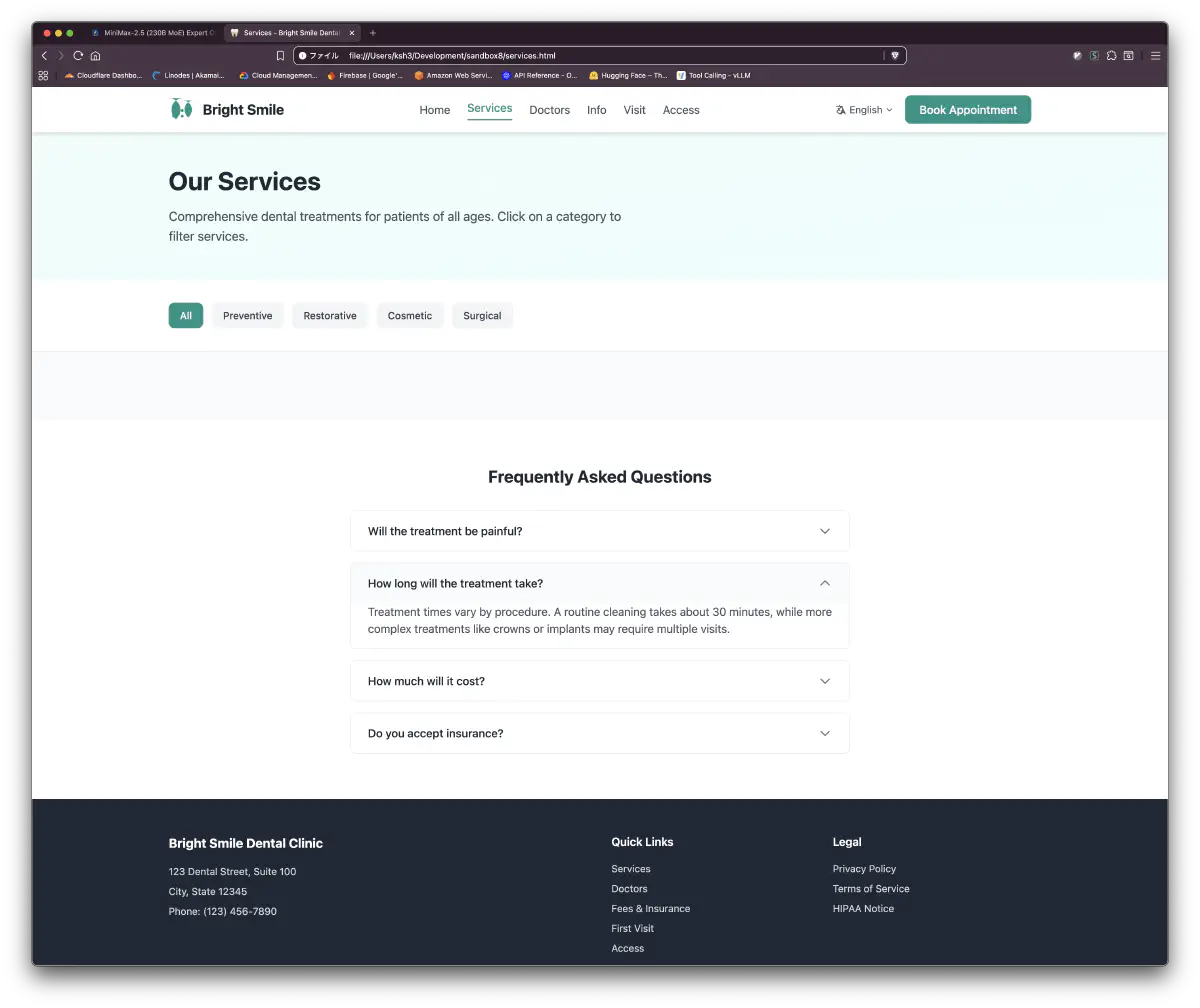
Results: 6 Pages in ~18 Minutes
| Page | Key Content | Alpine.js Interactions |
|---|---|---|
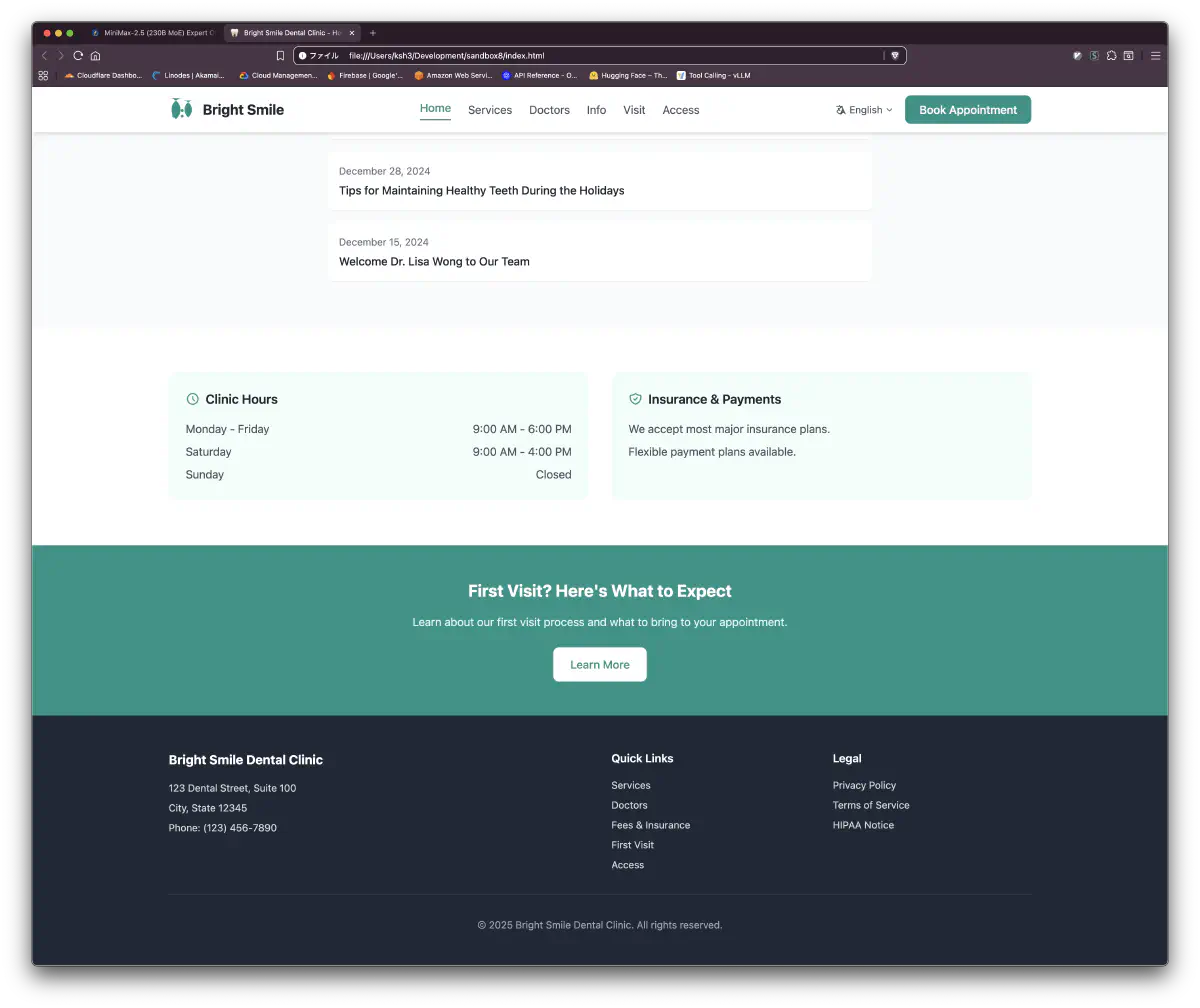
| index.html | Hero, 8 service cards, doctor previews, news | Mobile nav, language switch UI |
| services.html | 14 treatment cards, FAQ section | Category filtering, accordion |
| doctors.html | 6 doctor profiles, specialties | Expandable details |
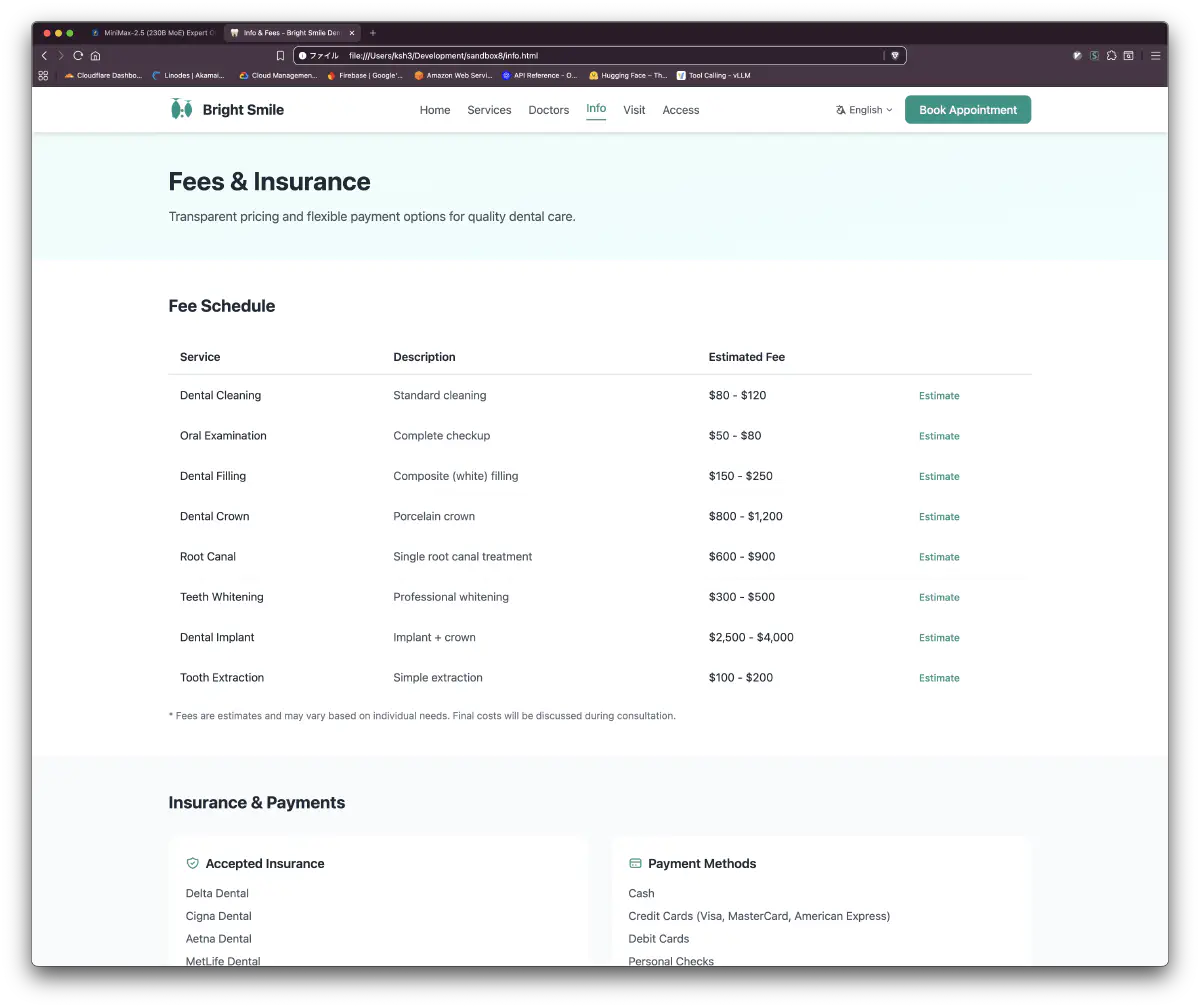
| info.html | Fee table, insurance, payment methods | Estimate modal |
| visit.html | First visit flow, reservations | Validated form |
| access.html | Map, transit, parking | Direction tab switching |
- Total time: 18 minutes 2 seconds (design, implementation, diagnostics)
- Diagnostics: Zero errors and warnings
- Quality: Even at IQ3_S, accessibility (ESC key close, focus management) and semantic HTML structure were maintained
Generated Site Screenshots
Quantization-Level Operating Guidelines
| Quantization | Model Size | TG Speed | Use Case |
|---|---|---|---|
| IQ5_K | 157.7 GiB | 34-37 tok/s | Benchmarking, quality-critical generation |
| IQ4_NL | ~120 GiB (est.) | Improved | Long-context work, React LP generation |
| IQ3_S | ~100 GiB (est.) | Further improved | High-volume structured code, speed-priority |
These tasks also used lower quantization to place more weights on GPU.
Impressions from site generation
A 229B model ran locally at 37 tok/s. Independent experts make CPU placement an option when VRAM is insufficient. Both generated sites kept their multi-file structure consistent in this test.
Reproduction
Model Download
  huggingface-cli download <quantizer>/MiniMax-M2.5-GGUF \
  --include "MiniMax-M2.5-IQ5_K.gguf" \
  --local-dir /mnt/data/hf/hub/models--MiniMax-2.5-GGUF
Benchmark
Use the Part 1 command with ik_llama.cpp Expert Offload support.
Measurement
  curl -s http://localhost:8081/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"minimax","messages":[{"role":"user","content":"Explain MoE architecture"}],"max_tokens":512}'
Technical Notes
Why –no-mmap
Loading 157GB with mmap produced intermittent page faults. --no-mmap reads it into RAM to avoid those inference delays, at the cost of several minutes of startup.
Expert count and Decode speed
MiniMax-2.5 selects 8 of 256 experts, versus GLM-4.7-Flash at 4 of 64. Selection costs more, but each expert is small (FFN 1,536 dimensions). Expert count alone does not determine Decode speed.